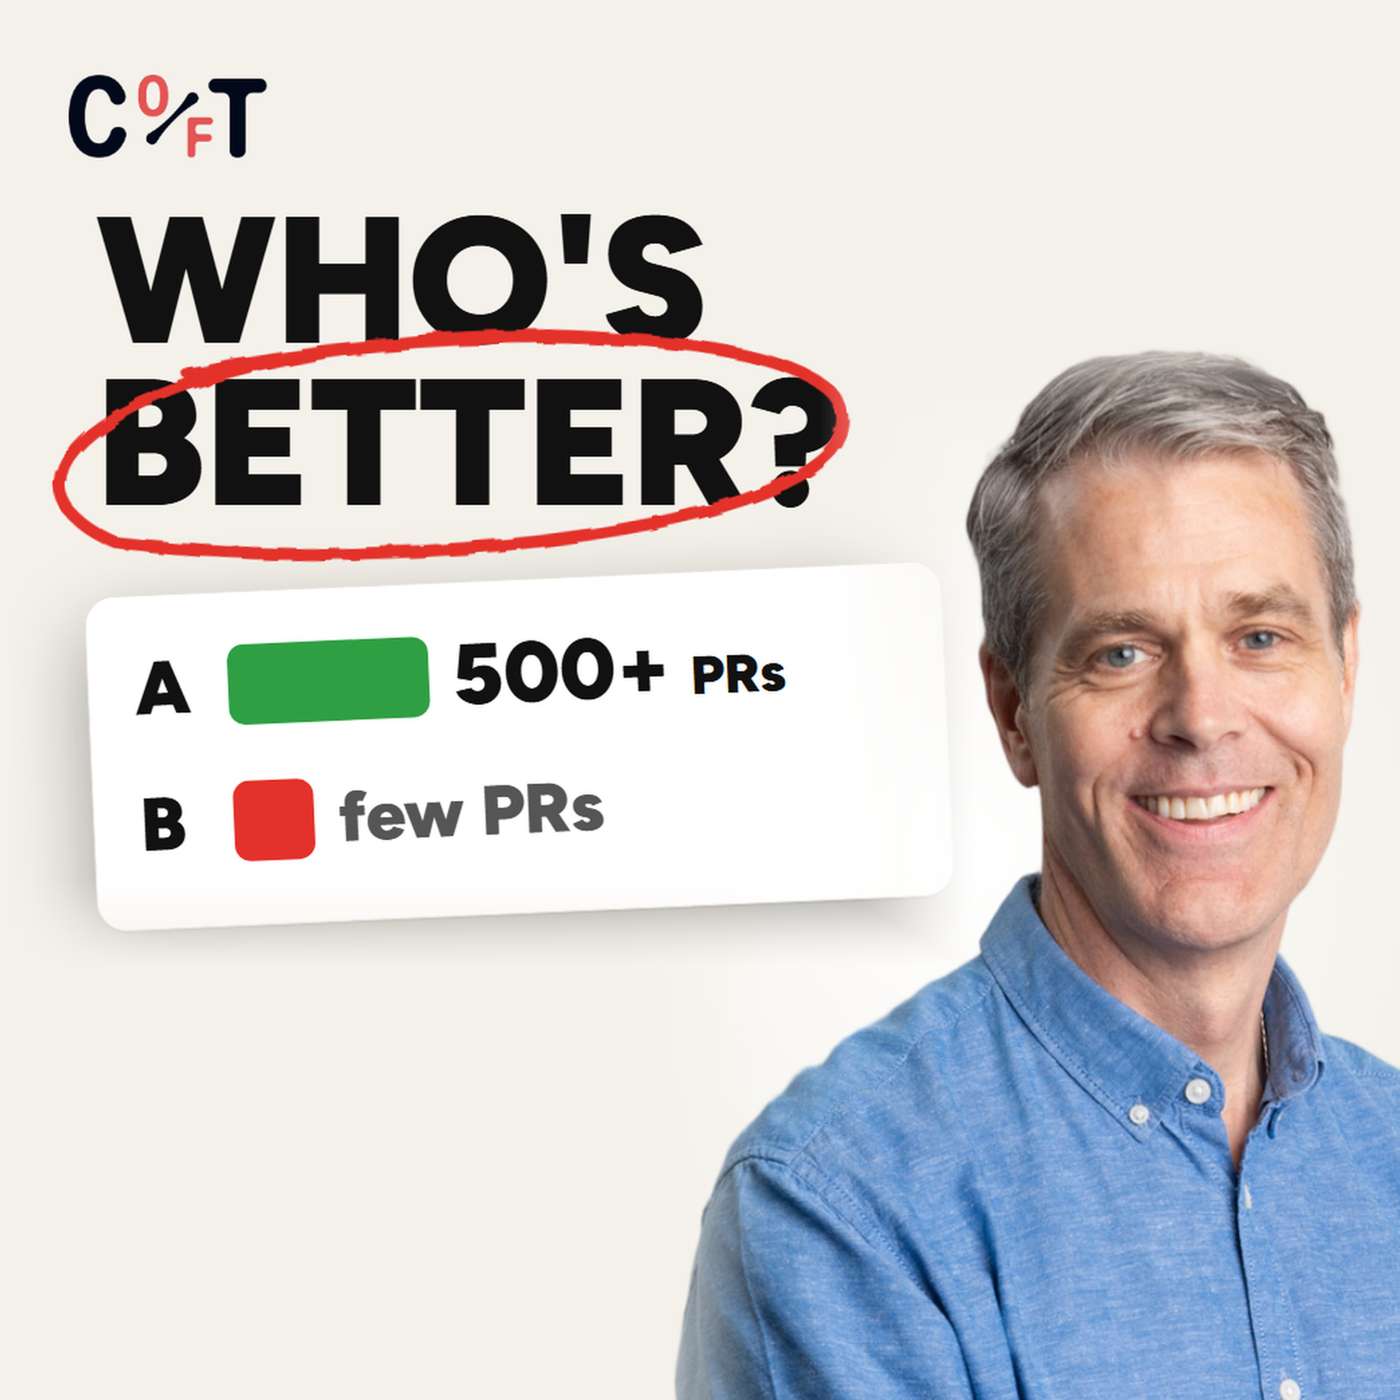
Your Best AI Engineer Might Have the Worst Metrics | Sonar CTO Andrea Malagodi
Evaluation and Summary
Andrea Malagodi, CTO at Sonar, joins Conor Bronsdon to explore why simple metrics for measuring AI engineer productivity—like cost per pull request—can be dangerously misleading. The episode opens with a concrete case study: Malagodi's finance team flagged two engineers with opposite metrics. One had 500+ PRs at low cost per PR but was actually running a personal agent factory that produced mostly tests and validation (two-thirds of output). The other had high spend and few PRs but was tackling genuinely hard problems requiring long, multi-turn AI reasoning sessions. Judged on cost alone, the first looks efficient; in reality, the second was doing more valuable work. The conversation traces a history of bad productivity proxies in software—lines of code, story points, token leaderboards—and argues that the people who *removed* code were often most important. Malagodi outlines Sonar's "guide, verify, solve" agent loop: Vortex for codebase context, algorithmic plus LLM-based PR analysis, a remediation agent for legacy debt, and Hunter for security vulnerabilities. Key technical insights include why breaking agent work into small pieces matters (a five-day session producing 400,000 lines leaves you blind to what's in your codebase), how to set up disagreement between agents using orchestrators with personas for engineering, product, and quality, and why mixing model families beats picking one. The episode covers enterprise rollout challenges: unified cost views for finance, 30% savings from cutting repeated context reads, and why tiny budgets ($50/week) are operationally hard. Practical governance topics include rotating triage duty to protect deep work, building organizational skills to sort hundreds of CVEs (many false positives), and defense-in-depth for AI-written code. The episode closes with personalized software for teams and individuals. Throughout, Malagodi grounds abstract principles in real engineering constraints: what works at scale, how to avoid false economies, and why human judgment remains essential when metrics diverge from actual value creation.
Verdict: A sharp, practically grounded conversation that dismantles a dangerous metric and offers real alternatives; essential for engineering leaders deploying AI at scale.
Technology rubric
-
Technical accuracy 4/5 20%
Concrete case studies and product details (Vortex, Hunter agent, guide-verify-solve loop) are grounded; no obvious errors, though depth is limited by show notes alone
-
Insight beyond the headlines 5/5 20%
Core insight—that cost-per-PR metrics hide real value and can incentivize the wrong behavior—is original and forward-looking; the history of failed proxies and why removals matter adds depth
-
Clarity for non-experts 4/5 15%
The 500-PR vs. high-spend engineer framing is immediately clear; agent terminology and enterprise concepts are accessible without dumbing down
-
Substance 4/5 15%
Dense with specific examples, technical architecture (guide-verify-solve, agent personas, model mixing), and operational lessons; covers governance, cost, and quality without filler
-
Delivers on its title 5/5 15%
Title promises that best engineers may have worst metrics; episode delivers exactly that thesis with detailed case study, explores why, and offers frameworks to measure better
-
Value for time 4/5 15%
57 minutes covering metrics, agent architecture, enterprise rollout, and governance; well-chaptered and substantive, though some sections (e.g., model mixing, CVE triage) could be tighter
Worth it if you lead engineering teams, manage AI spend, or care about measuring developer productivity beyond vanity metrics.
Content flags
- Ad-heavy Three sponsor reads (Svix, Walrus, Inngest, G2i) take up meaningful time in a 57-minute episode
Based on the episode description. AI-generated; it can be wrong.
Show notes
More from Chain of Thought | AI Agents, Infrastructure & Engineering
Chain of Thought host Conor Bronsdon interviews Kimberly Logan, Head of Product at the Walrus Foundation, about portable and verifiable memory for AI agents. The core problem: if an agent's memory lives inside one model provider's infrastructure, switching models or harnesses means losing that context and starting…
Worth it if you build or deploy AI agents, care about vendor lock-in, or want to understand why decentralized storage matters for agent infrastructure.